seven ways teams use OneBucket™
pick the one that matches your situation, see it running on real data, then prototype it with your own team in about a week.
- 1move data behind a fixed endpointa cloud exit, a cost move or a consolidation, and every application has the old bucket hard-coded
- 2write once, land in several cloudsthe board or a regulator wants a second copy outside the primary cloud, without a sync job per bucket
- 3placement by policy, per bucketa regulated or multinational business must keep certain data in a region or cloud, under its own keys
- 4cache next to computegpus in one cloud, data in another, idle time and egress on every run
- 5agents reach data through mcpagents or rag over data in several stores, and security will not hand out raw cloud keys
- 6fewer tokens: know before fetchingagents burn tokens finding data and carry every wrong file through every later turn
- 7parquet across clouds, one buckettabular data in several stores and every analysis starts by exporting and stitching
move the data behind a fixed endpoint, with no downtime
the situation
a cloud exit, a cost move to a cheaper object store, or a consolidation after a merger. every application has the old bucket hard-coded, so the migration becomes a change program with a cutover.
what OneBucket changes
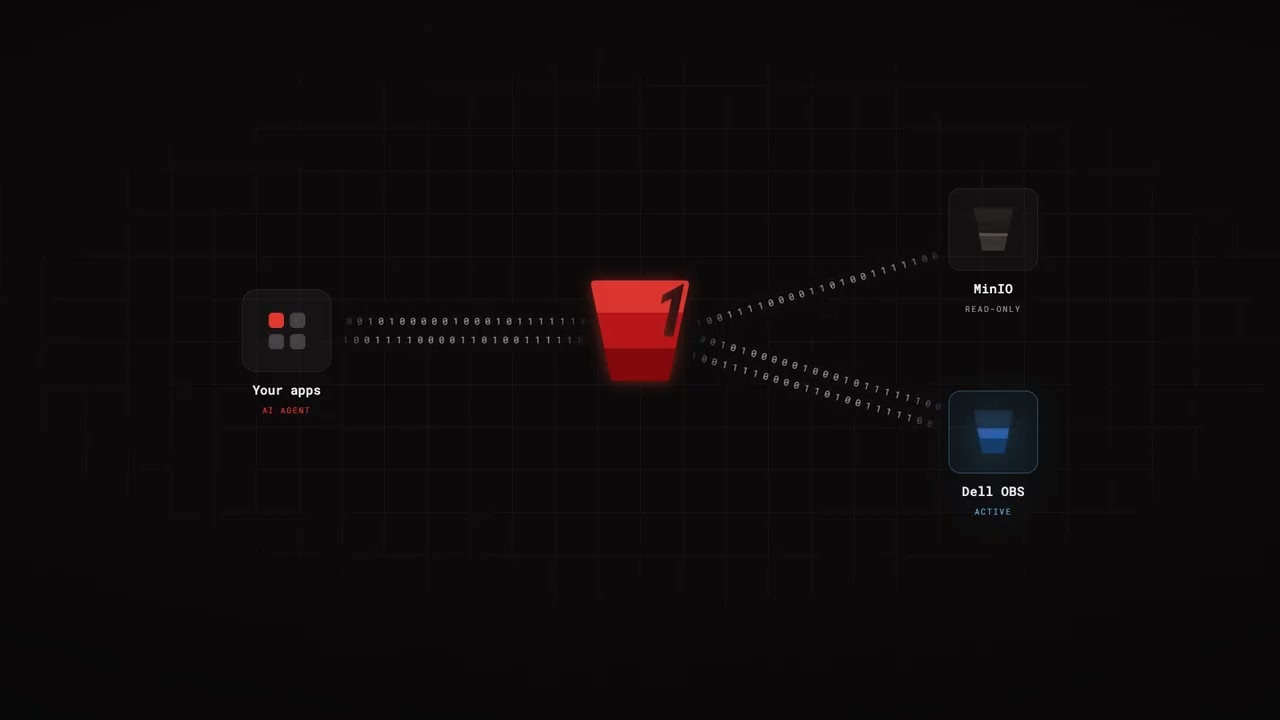
applications point at one endpoint that never changes. behind it you add the new backend, let OneBucket sync in the background, then drain and retire the old one. reads and writes continue throughout. a store can also be added as a tier rather than a replacement.
watch a live s3 migration

write once, land in several clouds
the situation
the board wants a second copy of critical data outside the primary cloud, for resilience, for negotiating leverage, or for a regulator. today that is a sync job per bucket, a second set of keys in every application, and a failover plan nobody has tested.
what OneBucket changes
one policy maps the bucket to several peer buckets, each synchronous or asynchronous, with a write quorum you set. applications write once and the copies land. a new provider joins by adding a peer bucket, and opportunistic replication fills it from existing data as it is read.
placement by policy: each bucket lives where the rule says
the situation
a regulated or multinational business must keep certain data in a given region or cloud, under its own keys, while the rest of the business runs on a global platform. today that means separate buckets, separate pipelines and a compliance review per application.
what OneBucket changes
the rule is written once, at the layer, per bucket. a sovereign bucket is mapped to eu backends under the customer's keys; the global bucket goes wherever policy says. replication adds copies where they are required. applications and agents still use one endpoint, and keys stay with the customer.
gpus in one cloud, data in another: cache next to compute
the situation
training or inference runs in a gpu cloud, while the data sits in aws, in another cloud and on-prem. jobs wait on remote reads, gpus sit idle, and every epoch pays egress again. moving the data wholesale is not an option.
what OneBucket changes
a cache-mode peer bucket sits in the gpu cloud, under the same namespace. prefetch warms it before a job, by policy or on request; reads are served locally and stay in sync with the source. the source remains the system of record and nothing is rearchitected.
read how rivet did itagents reach the data through mcp, inside limits you set
the situation
the business wants agents and rag over documents and datasets spread across stores. security will not hand an agent raw cloud keys, and nobody wants to copy everything into one place first.
what OneBucket changes
the data plane speaks mcp natively, with oauth 2.1 and audience-bound tokens. a policy sets the outer limits per key; inside them the agent lists, reads and writes at runtime. every call is logged, and a key can be dropped to read-only instantly.
fewer tokens: know the data before fetching it
the situation
agents pay for every byte they read, then pay again on every turn. scattered data means listing silos, opening the wrong files, and dragging them through the whole conversation.
what OneBucket changes
ask first, fetch once. metadata answers where and how big; only the matching object enters context. large files and heavy work stay outside the model and only the result comes back. hot data is pre-positioned for the next turn. in a worked five-step example, roughly 8x fewer input tokens, and the gap widens on every follow-up.
illustrative worked example, not a benchmark. we would rather measure it on one of your agent workflows.
parquet across clouds, queried as one bucket
the situation
tabular data lands as parquet in different places: one business unit on aws, another on gcs, history on-prem. every analysis starts by exporting, copying and stitching sources together.
what OneBucket changes
all of it appears under one bucket and one prefix layout. any s3-reading engine (duckdb, spark, databricks, polars, trino) reads the files together in one query. nothing is copied first. the join across stores disappears because there is nothing to stitch.
see it with databricksa OneBucket sandbox for your team
on our already deployed saas, nothing to install. request an account and you get one organization to explore.
one to explore, one per prototype. each with its own users, keys and policies, so nothing from one prototype touches another.
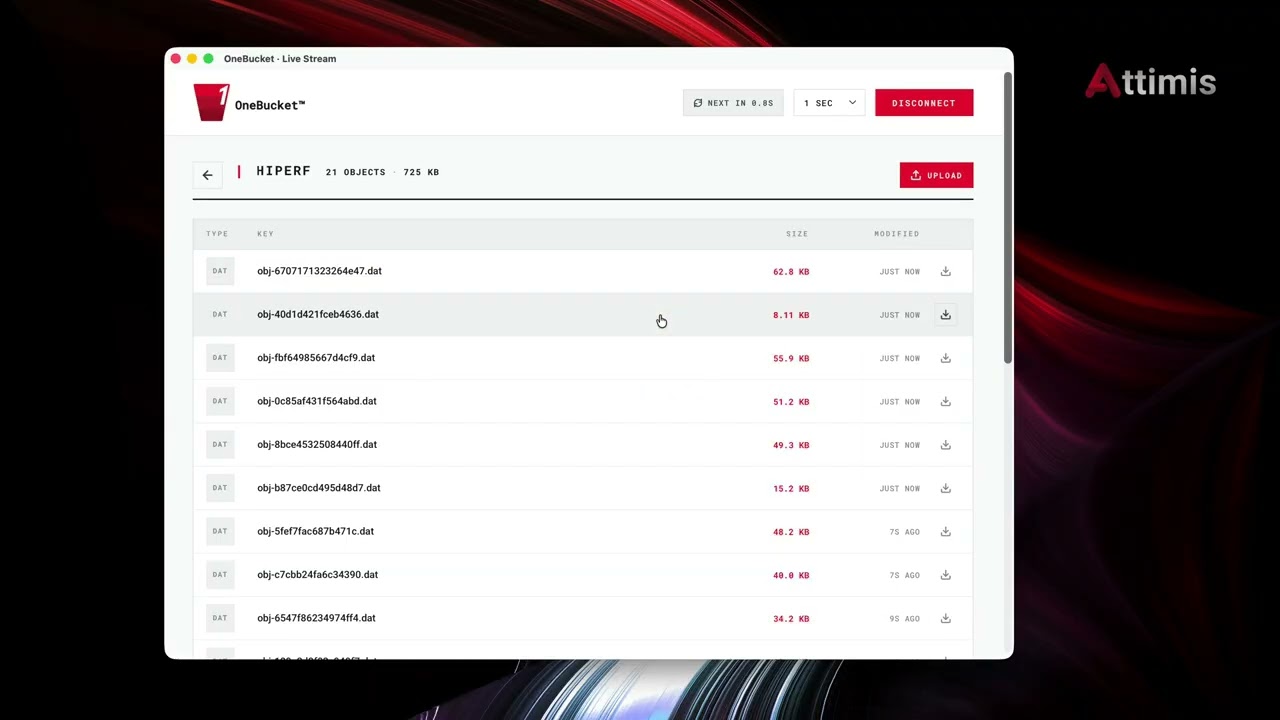
the s3 endpoint for any tool or engine, and the OneBucket mcp connector in Claude or any mcp client. the web explorer for browsing.
point it at your own buckets from day one, or ask us for starter backends across clouds while you get going.
we onboard your team personally and stay reachable over a shared channel with attimis engineering.
how a first prototype runs
four steps, about a week end to end. the result is a working demo on real data, not a slide.
pick the scenario
one use case, one of the seven patterns. we are glad to help shape the demo story in a short call.
the organization is ready
a fresh organization for the prototype, with its keys and policies, ready the same day. mcp connector and s3 endpoint included.
you point it at data
your own buckets, or starter backends from attimis. nothing is copied first; backends are added behind the endpoint.
demo it
your team presents, attimis engineering is on call. the questions keep coming; the sandbox answers them.
see it work
getting-started guides, customer and platform solutions, and demos on live data.
pick a scenario. demo it next week.
request an account and we'll have an organization ready for your prototype the same day.
request an account